Tag: Prompt Caching
-
GPT-6 Astra API Pricing & Discounts: How to Avoid the 272K Context Cost Jump
GPT-6 Astra API pricing explained: Standard, Fast, Batch, caching, the 272K context cost jump, and discounted Astra access through LLMFly AI.
-
Claude Fable 5.1 API Migration Guide: Breaking Changes, Fallbacks, and Cost
Migrate to Claude Fable 5.1 safely: model ID, breaking changes, thinking blocks, refusals, fallbacks, caching, cost, and rollout.
-
Claude Fable 5.1 API at 50% Off: Pricing, Setup, and Use Cases
Access the Claude Fable 5.1 API through LLMFly AI at 50% off. Compare official pricing, cache savings, setup steps, use cases, and production checks.
-
Prompt Caching for AI APIs: When It Saves Money—and When It Costs More
Last reviewed: August 30, 2026. API interfaces and product settings change; verify current official documentation before production deployment. LLM prompt caching can reduce repeated input processing, latency, and cost when many requests share a stable prefix. It can also add cache-write cost without meaningful hits when prompts change constantly or traffic is too sparse. Measure…
-
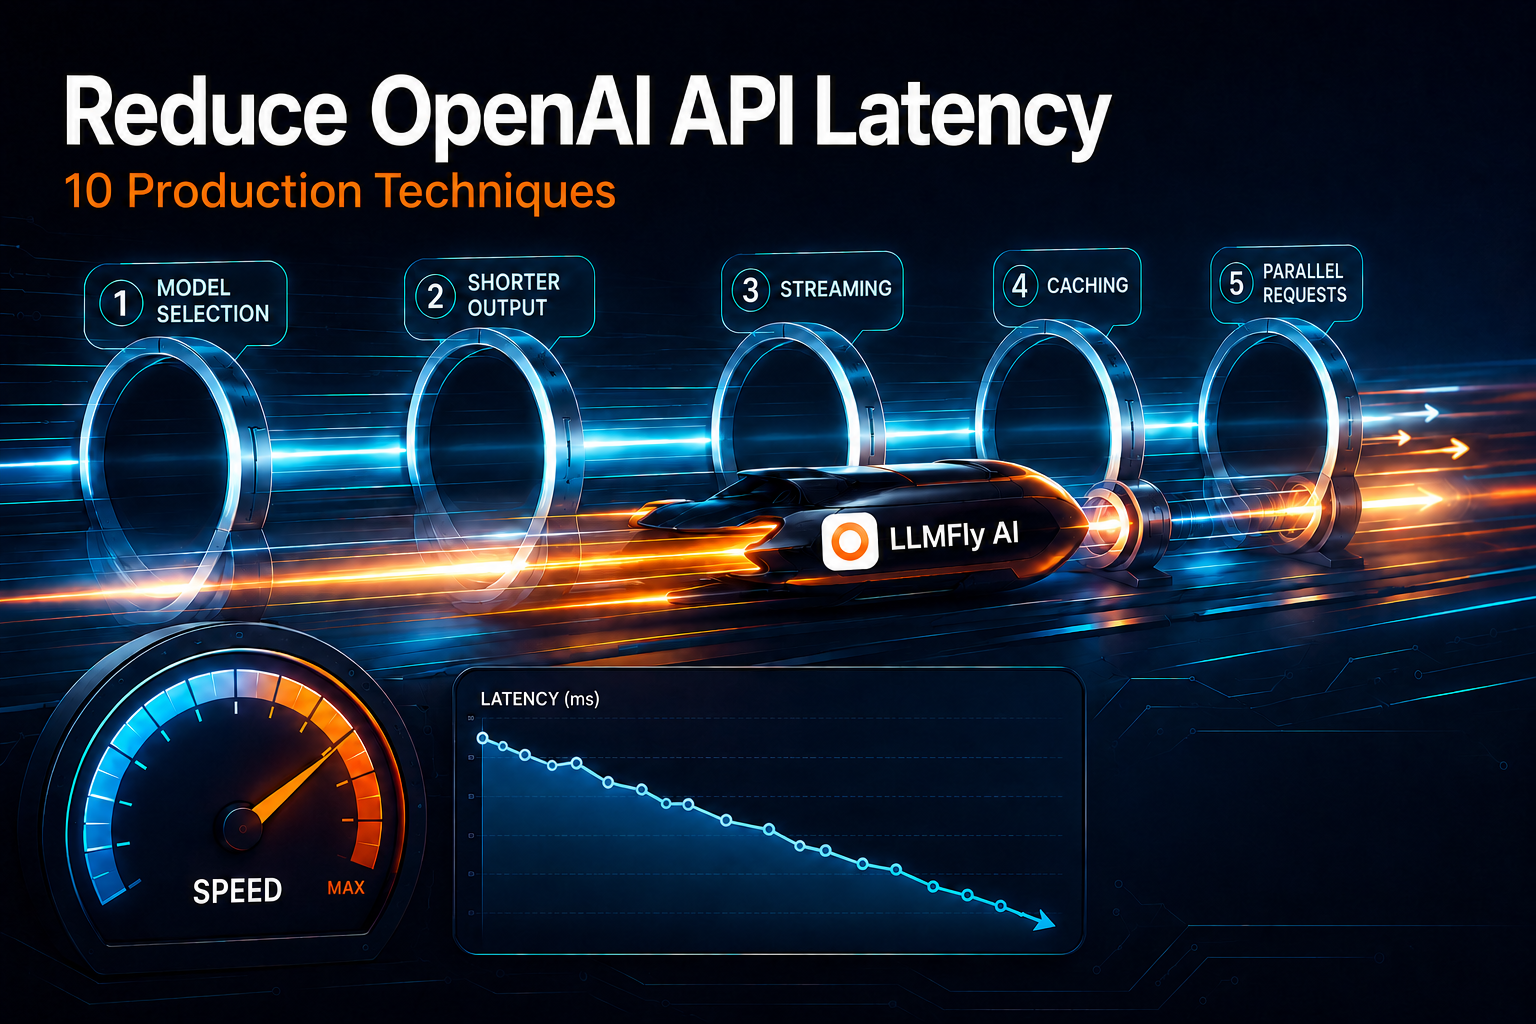
How to Reduce OpenAI API Latency: 10 Production Techniques
Reduce OpenAI API latency with model selection, shorter outputs, streaming, caching, parallel calls, connection reuse, timeouts, and production tracing.