Category: Cost & Performance
-
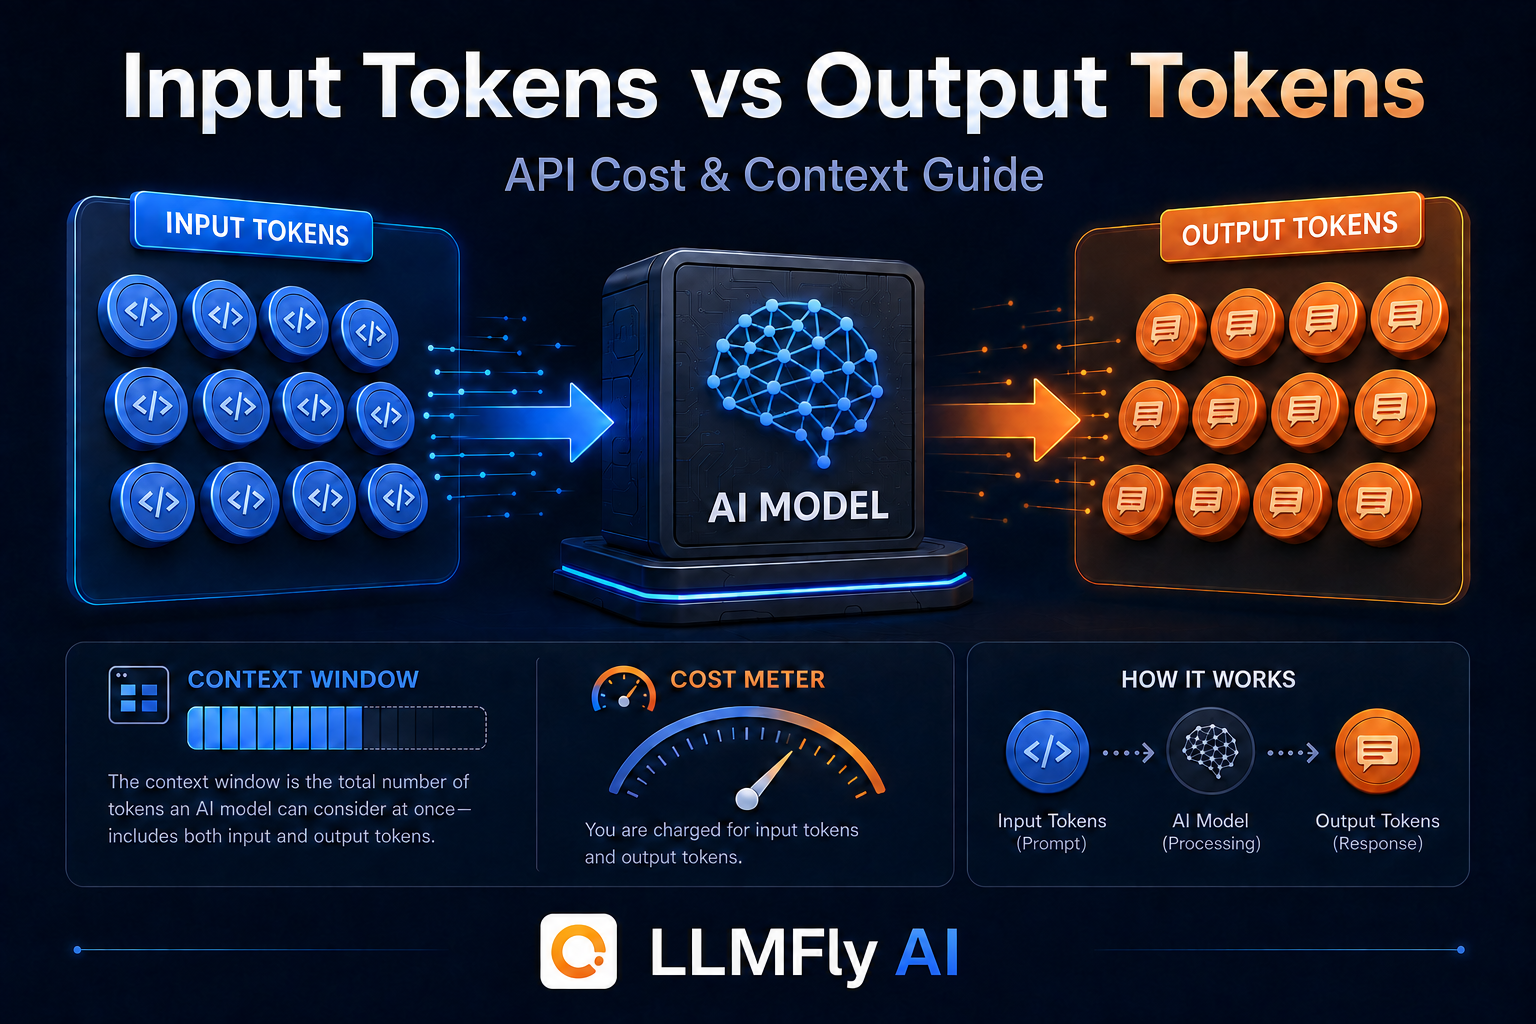
Input Tokens vs Output Tokens: How AI API Pricing Really Works
Understand input tokens vs output tokens, context windows, cached tokens, reasoning usage, agent loops, cost formulas, and practical ways to lower API spend.
-
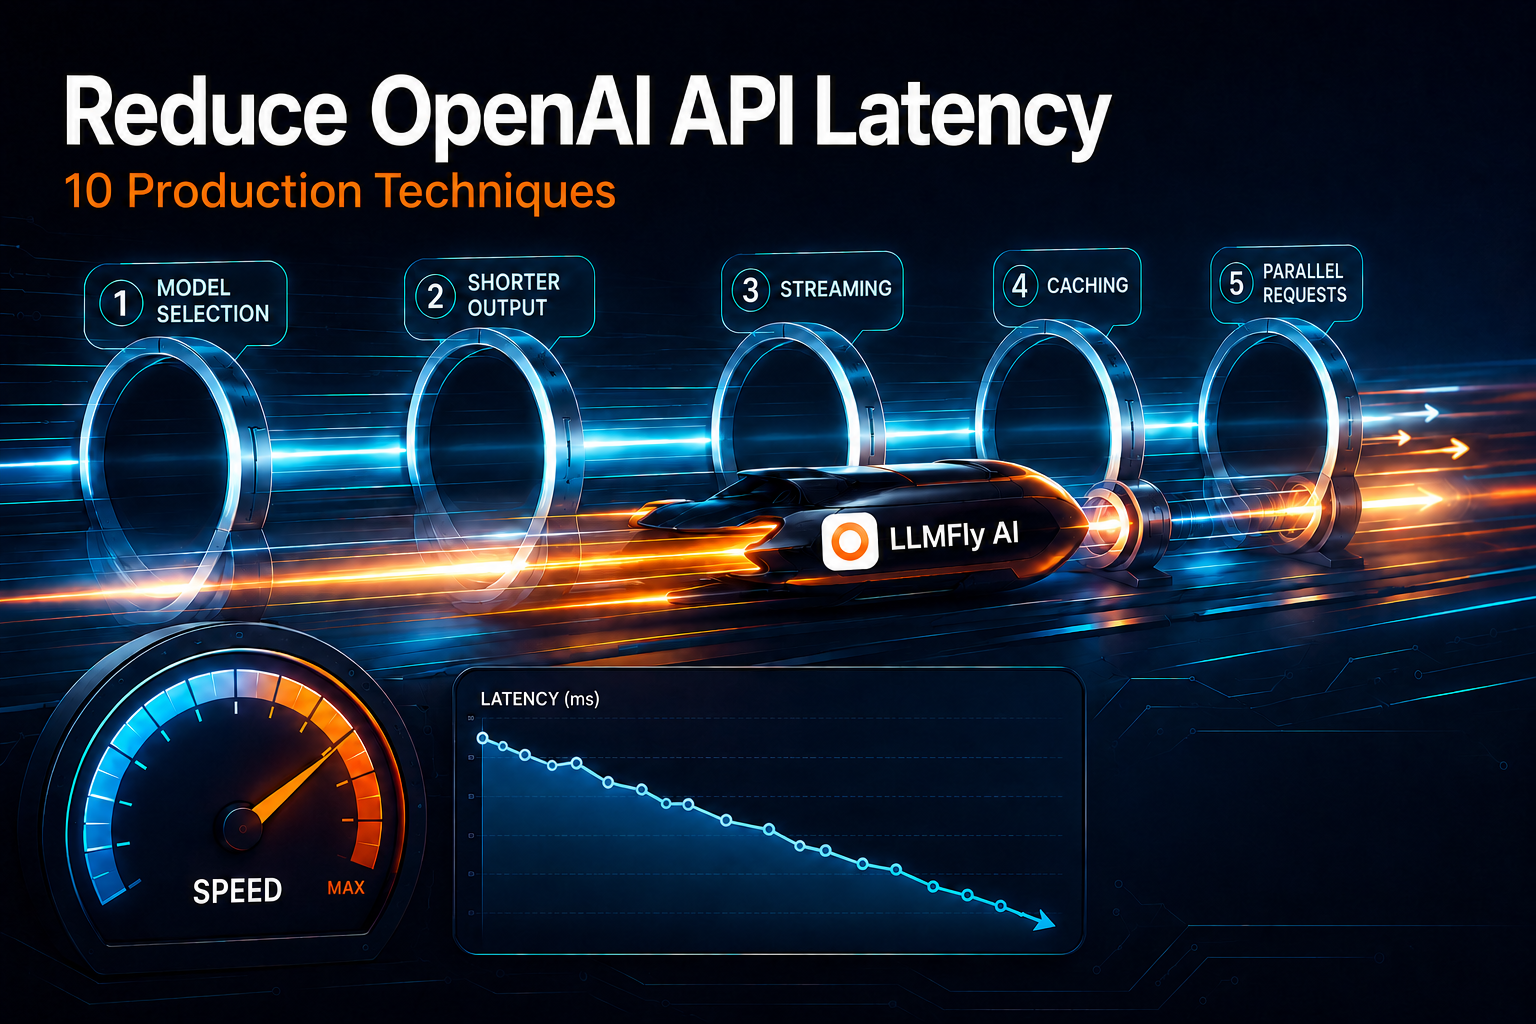
How to Reduce OpenAI API Latency: 10 Production Techniques
Reduce OpenAI API latency with model selection, shorter outputs, streaming, caching, parallel calls, connection reuse, timeouts, and production tracing.
-
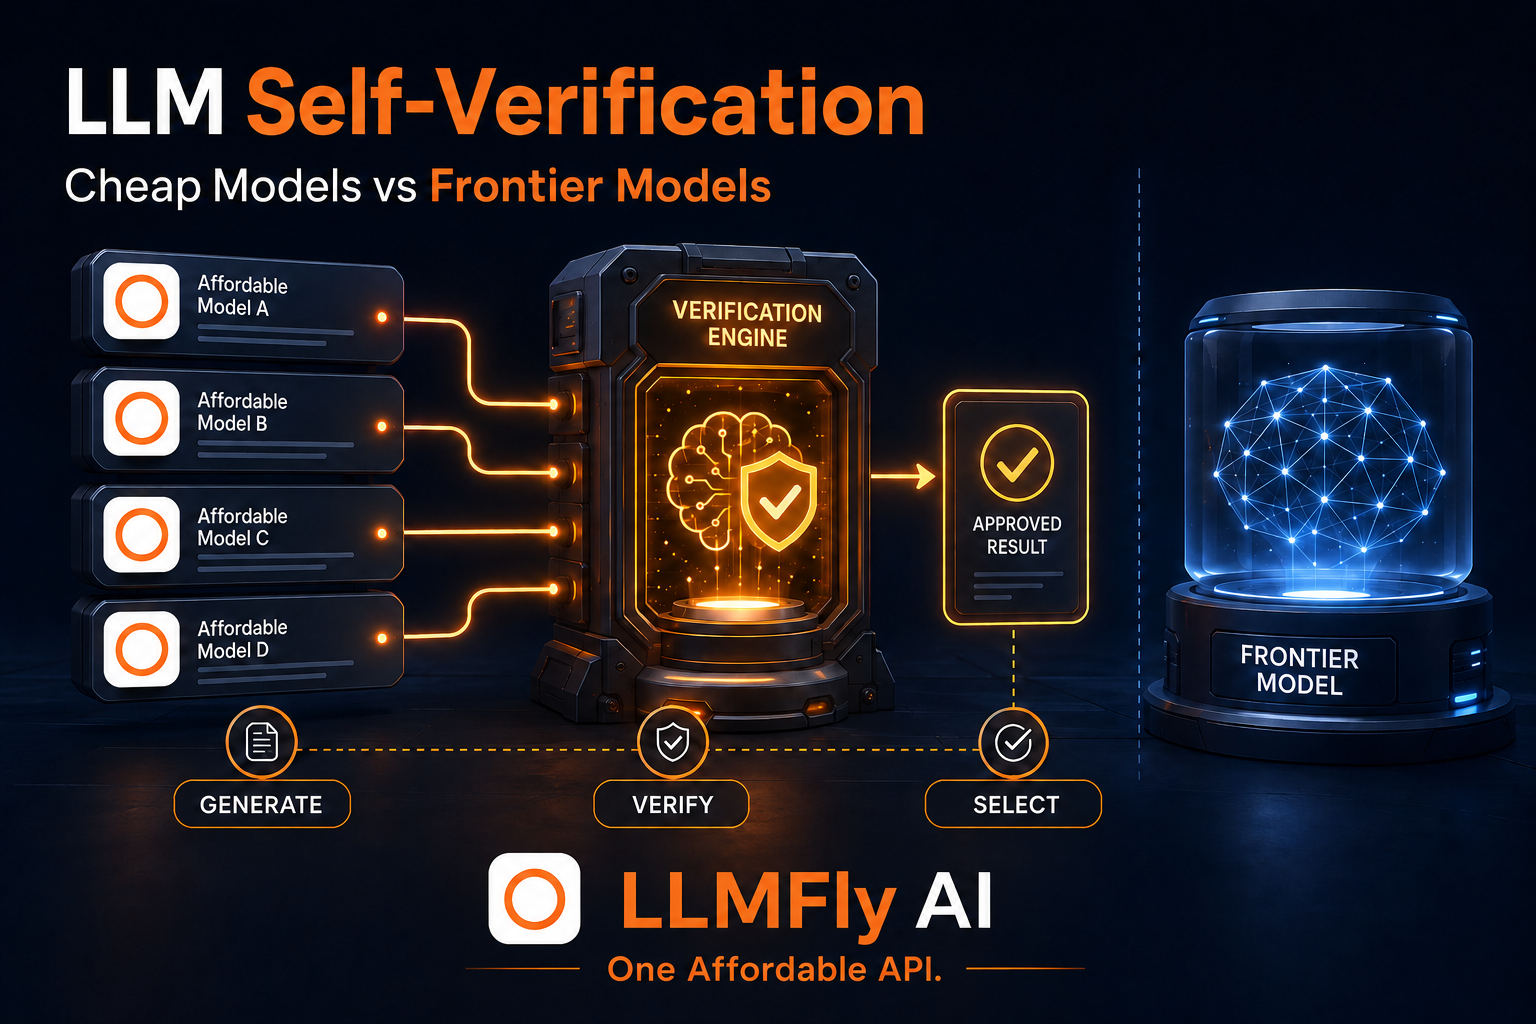
LLM Self-Verification: Can Cheap Models Beat Frontier Models on Cost?
Learn when multiple affordable-model candidates plus validation can cost less than one frontier-model call, and how to test the tradeoff safely.